Overview
Building owners, service contractors and controls integrators have moved beyond “if” for analytics in HVAC predictive maintenance (PdM). The pressing question in August 2026 is still where to run those analytics: on-device at the edge, centrally in the cloud, or in hybrid arrangements. Since June 2026 the calculus has shifted further: cheaper and more powerful edge hardware, wider private 5G/CBRS adoption for campuses, and clearer regulatory expectations around automated decisions. This update gives a practical, ROI-focused comparison, current benchmarks and a concrete pilot plan so you can make a defensible architecture choice for your portfolio.
Background: what changed since mid‑2026
Three developments accelerated deployment choices in the past two months:
- Edge hardware keeps getting cheaper and faster. Commodity Arm NPUs and small accelerators (Edge TPUs, Coral successors, and Orin/Orin‑class modules) are now commonly available in gateway BOMs well below $150 per unit for high-volume buys. Low-power NPUs optimized for TinyML inference make local deep‑learning practical on retrofit gateways.
- Campus connectivity options expanded. Adoption of private 5G (CBRS in the U.S.) and managed LTE‑M/NB‑IoT for metered sites reduced telemetry cost for many centralized portfolios—some campuses now see per‑site data costs under $8/month for routine telemetry, making cloud-first viable in more places—but metered cellular and rural sites still face $20–60/month ranges for richer telemetry.
- Governance and compliance pressure rose. Regional AI rules and procurement clauses now explicitly call for audit trails, explainability for automated interventions and change control for model updates. Organizations that treat model deployment like firmware (signed artifacts, rollback plans, logged inference inputs/outputs) face fewer procurement and insurance hurdles.
Data and evidence: what drives ROI in 2026
When evaluating architectures, quantify these variables at the site or portfolio level. These remain the levers that determine payback and scale economics:
- Per‑site telemetry economics: include SIM/data plan, gateway amortization, private 5G leases or CBRS spectrum management fees, and any cloud egress charges. Expect a wide range: $6–12/site/month for campus-managed telemetry vs. $20–60/site/month for high-frequency metered cellular in distributed portfolios.
- Failure economics: average cost per emergency service call (labor, overtime, travel, parts), SLA penalties and revenue impact. In many portfolios each emergency call still costs $500–1,000; for critical systems (medical buildings, data centers) the number can be much higher and justifies faster edge actions.
- Telemetry profile: high-frequency waveforms (vibration, motor current) favor edge preprocessing or on-device inference; low-frequency telemetry (temperatures, setpoints, alarms) is cheap to send and benefits more from cloud cross-site models.
- Human processes: baseline dispatch volumes, first‑time‑fix rates and spare-parts policies. PdM value is realized when analytics change what technicians do—parts staging, targeted workflows and replacement intervals.
Concrete pilot datapoints: emergency calls per 100 units/year, mean downtime per event (hours), average cost per event, monthly telemetry cost per site, and technician fully-burdened hourly rates.
Multiple perspectives: what stakeholders now emphasize
- OEMs continue to embed basic anomaly detection in controllers and emphasise local safety protection—OEMs also push integration APIs so cloud providers can benchmark across installations.
- Analytics vendors point to fleet learning and cross-site benchmarking as their competitive advantage; several now offer hybrid toolchains that support secure over‑the‑air edge deployments and targeted raw-data capture for retraining.
- Integrators and service providers increasingly sell outcome contracts (uptime or response SLAs) and therefore prefer hybrids that combine edge protection with centralized model improvements to meet guaranteed metrics.
- Owners/operators weigh capex constraints, portfolio homogeneity and telemetry costs. Large, connected campuses increasingly choose cloud-first; distributed portfolios still favor edge or hybrid approaches for faster, local value.
Why analytics location still matters (updated)
- Latency & safety: Edge inference supports sub-second protective actions (compressor stall mitigation, motor thermal limits). Cloud roundtrips cannot reliably support those protections where equipment safety or life‑safety is involved.
- Bandwidth & cost: Continuous waveform uploads for spectral analysis remain expensive. Edge feature extraction and event‑triggered raw dumps lower data volumes by an order of magnitude in most real deployments.
- Resiliency: Local diagnostics and queued telemetry keep monitoring functioning during WAN or cloud outages—important for mission‑critical facilities and for maintaining technician workflows.
- Model lifecycle: Centralized training still simplifies rare‑failure learning, but federated learning pilots and on-device continual learning are beginning to reduce the need to move all raw data to the cloud for every retrain.
- Governance & auditability: Procurement and insurers now expect signed model artifacts, inference logs and human‑in‑the‑loop overrides for automated control—architectures that enable these audit trails reduce legal and commercial friction.
Updated decision matrix: edge, cloud, hybrid (Aug 2026)
- Edge‑first — prefer when:
- Failures require fast local action or have safety implications.
- Sites are metered, rural or have expensive cellular telemetry.
- You target rapid reduction in emergency calls within 3–6 months and can accept higher upfront gateway capex.
- Cloud‑first — prefer when:
- Portfolio is centralized, homogenous (campus or central plant) and has managed private 5G/CBRS or fiber.
- Low upfront capex is a strict constraint and you value rapid cross‑site benchmarking and centralized retraining.
- Telemetry costs are under roughly $10/site/month for your typical data profile.
- Hybrid (most common and pragmatic) — prefer when:
- Edge handles time‑critical inference and feature reduction; cloud handles training, fleet analytics and enterprise workflows.
- Edges send triggered raw dumps or scheduled samples to the cloud for retraining—this minimizes egress while preserving fleet learning.
Performance KPIs to track in 2026
- Precision & recall for fault detection; monitor drift and false-positive rates after each model update.
- Mean time to detect (MTTD) and mean time to repair (MTTR).
- Emergency call reduction and prevented downtime hours per year.
- Technician dispatch hours saved, first‑time‑fix rate and parts‑per‑call.
- Net TCO over 3 years: hardware, connectivity, cloud fees, implementation and savings from avoided emergency costs.
- Model governance metrics: number of rollbacks, time from tested model to production, and percentage of inferences logged for audit.
Illustrative ROI scenario — rebenchmarked for Aug 2026
Use this as a comparative example—update with your actuals.
- Fleet: 200 RTUs across 50 distributed sites.
- Baseline: 4 emergency calls/site/year at $700/call (higher labor and parts costs in 2026), 1.5 downtime days per event.
- Goal: 40% reduction in emergency calls via PdM.
Option A — Cloud‑only: minimal hardware capex ($0–$150/site). Subscription + telemetry $30–35/site/month for richer telemetry; annual OPEX ≈ $84k–$102k.
Option B — Hybrid (edge gateways $400–$600/site one‑time with selective waveform capture): lower ongoing telemetry $10–15/site/month. One‑time capex ≈ $80k–$120k; annual OPEX ≈ $24k–$36k. Hybrid pilots in 2026 commonly show 20–40% emergency‑call reduction within 6–12 months when technician workflows are integrated.
Outcome: For distributed fleets with metered cellular or high per‑event costs, hybrid often returns faster payback (12–24 months). For campuses with private 5G/fiber and low telemetry fees, cloud-first keeps capex down and accelerates fleet learning.
Operational best practices and checklist (new items for 2026)
- Standardize sensor names and tagging across sites—this still reduces labeling cost and prevents model underperformance.
- Implement edge feature extraction and event windows; use scheduled raw dumps or triggered uploads for retraining.
- Treat model deployments as firmware: signed binaries, certificate rotation, rollback procedures and staged rollouts (canary/A‑B testing).
- Integrate PdM outputs with CMMS and mobile work order tools so technicians get recommended parts and stepwise diagnostics.
- Instrument technician feedback: capture structured labels (true/false positive, root cause) at intervention time and feed them into retraining pipelines.
- Ensure explainability: log inputs/outputs and simple human‑readable rationales for automated actions to satisfy auditors and technicians.
- Design for security: secure device management (mutual TLS, TPM-backed keys), signed images and remote attestation reduce operational risk and procurement pushback.
Vendor selection checklist (practical 2026 criteria)
- Secure device and model lifecycle management with signed artifacts, rollback and canary deployments.
- MLOps tooling that supports federated learning or selective raw-data sampling to reduce egress costs.
- CMMS integrations and technician feedback loops for labeling and continuous improvement.
- Clear SLAs and audit capabilities for inference logging and change control to meet procurement and insurance needs.
Implications for decision‑makers
Consider your situation: for distributed assets with costly emergency calls and metered connectivity, hybrid or edge‑first architectures still tend to deliver the most measurable ROI. For centralized plants and campuses with private 5G or fiber, cloud‑first reduces upfront spend and speeds cross‑site learning. In both cases the differentiator is discipline: consistent instrumentation, technician workflow integration and ongoing measurement of false alerts and human time are what turn detection into dollars saved.
Outlook: what to watch next 12–18 months
- Edge accelerators will continue to improve price/performance, allowing more sophisticated on‑device models.
- Federated and on‑device continual learning pilots may reduce the need for raw-data egress for many maintenance classes.
- Model governance tooling and explainability frameworks will become procurement table stakes—expect auditors and insurers to request evidence of traceability.
- Outcome‑based service contracts will expand, pushing vendors and integrators to combine edge protection with cloud learning to meet performance guarantees.
Final recommendation
There is no universal answer. Run a focused pilot that mirrors your most common failure modes and includes technician feedback. Instrument 10–20 representative sites and split them between edge‑first and cloud‑first configurations. Track the KPIs above for 6–12 months, measure emergency‑cost savings and telecom spending, and choose the architecture that delivers the fastest, verifiable payback for your specific portfolio.
Frequently asked questions
How much raw data do I actually need to send to the cloud?
Usually much less than vendors initially propose. Extract features at the edge (RMS, FFT bins, envelope stats, event windows) and send those. Reserve raw waveform dumps for triggered anomalies or periodic sampling for retraining—this typically reduces data volumes by 10x–100x while preserving model utility.
Can I retrofit existing controls with edge AI, or do I need new hardware?
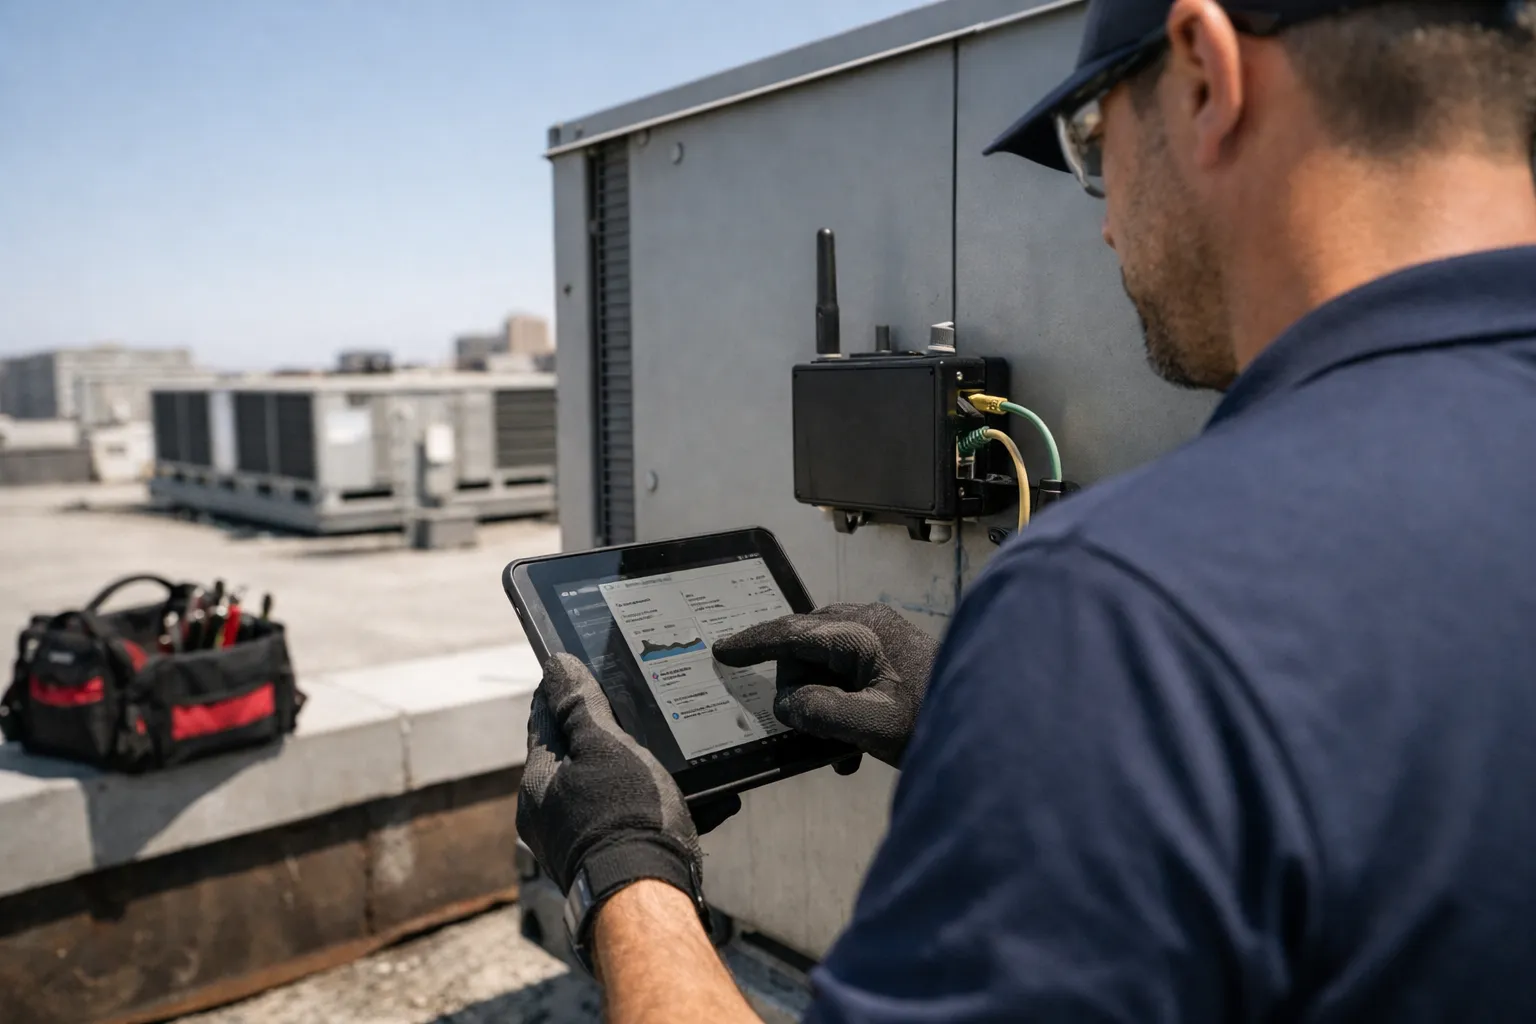
Many fleets can be retrofitted with low‑cost gateways that ingest existing sensor signals and run on‑edge inference. However, check signal quality and mounting: vibration and current‑signature analytics often need dedicated sensors and proper installation. Factor gateway integration, sensor upgrades and commissioning into up‑front capex.
How do I limit ongoing cloud fees?
Measure TCO over a 3–5 year horizon and include cloud OPEX in your business case. Use hybrid architectures to do feature extraction on‑site and send only events. Negotiate enterprise pricing for storage and egress, use tiered retention policies, and consider private 5G or campus networks where concentrated telemetry justifies the investment.
What role should technicians play in improving models?
Technicians are essential. Capture structured feedback (true/false positives, root cause) at the time of service and feed those labels into retraining pipelines. This human‑in‑the‑loop process is often the fastest way to reduce false positives and improve first‑time‑fix rates.
Is on‑edge automated control safe from a liability standpoint?
Automated local actions are technically feasible, but require documented safety cases, signed model artifacts, robust rollback and override procedures, and audit logging. Treat on‑edge control like any safety system: define owner‑approved actions, test under controlled conditions, maintain traceability and involve legal/risk early in procurement.